The last mile of a long road: faster NumPy in the browser


For a long time, running NumPy in the browser meant running it without an accelerated BLAS. Matrix multiplications fell back to plain loops (portable, but blind to cache and SIMD).
That just changed. The Emscripten-forge NumPy package now links OpenBLAS in WebAssembly, and at n = 1024 square np.matmul jumps to about 30.92× faster (float32) and 14.90× faster (float64). The next OpenBLAS release, already available as an experimental package on Emscripten-forge, with kernels contributed by QuantStack, pushes it further, and an optional Relaxed SIMD build adds another step on engines that support it.
What is Emscripten-forge?
Emscripten-forge is a software distribution for WebAssembly. Together with conda-forge, it rebuilds the conda ecosystem for WebAssembly, so compilers, runtimes, and shared libraries ship as redistributable conda packages with a coherent ABI (not Python wheels, not R packages, but native libraries that any language ecosystem can link).
Bringing a scientific language to the browser is hard enough that, so far, it has mostly happened one language at a time. Pyodide pioneered it for Python. Later on, WebR did it for R, on the same premise. Each is a self-contained, language-specific distribution. Emscripten-forge takes a different shape: a language-agnostic distribution. It builds on the foundational work of the Pyodide and WebR projects, and goes further, covering not only Python and R, but also C++, OCaml, Lua, compiler toolchains, and many more tools (and shipping with a package manager).
The missing compiler: Fortran on wasm32
Fortran sits at the core of foundational scientific packages: LAPACK, historically much of SciPy (although this is changing as SciPy has made strides to become Fortran-free), and R's compiled statistical routines are all Fortran underneath. Bringing any of them to WebAssembly therefore means bringing a Fortran compiler that can target wasm32.
For a while, Pyodide worked around the absence of such a compiler: its SciPy build was produced with f2c, a Fortran-to-C translator, so the Fortran source was transpiled to C and compiled with the existing Emscripten toolchain. That workaround enabled SciPy to run in the browser, but it was not enough for R, whose distribution could not sidestep a real Fortran compiler. That constraint is what started the work on Flang (LLVM's Fortran frontend) for WebAssembly, in the context of bringing R to the browser on Emscripten-forge.
OpenBLAS in WebAssembly
OpenBLAS is a widely used, optimized implementation of BLAS (Basic Linear Algebra Subprograms). BLAS is organized in three levels: Level 1 covers vector–vector operations (for example AXPY and dot products); Level 2 covers matrix–vector operations (for example GEMV, as in A @ x); Level 3 covers matrix–matrix operations (for example GEMM, as in np.matmul), which dominate large dense linear algebra. OpenBLAS also ships LAPACK (Linear Algebra PACKage): higher-level routines for solving linear systems, factorizations, and eigenproblems, and most np.linalg calls ultimately delegate to those LAPACK entry points.
Building a Fortran toolchain for WebAssembly was itself a multi-person effort. Isabel Paredes and Serge Guelton wrote the initial Flang patches for WebAssembly, inspired by George Stagg's work on Fortran in WebAssembly; Serge Guelton also upstreamed parts of that work into LLVM. Isabel Paredes now maintains the up-to-date recipe on Emscripten-forge, flang_emscripten-wasm32.
But even with a working Flang, the toolchain alone was not enough to bring OpenBLAS to the browser. The first OpenBLAS and LAPACK builds could not be used immediately: WebAssembly enforces stricter calling conventions than native targets, and additional patches were needed to make the library compile, archive, and link under Emscripten. Ian Thomas adapted OpenBLAS for Flang and Emscripten; those patches live in the Emscripten-forge OpenBLAS recipe (the bridge between upstream OpenBLAS and the NumPy builds measured in this post).
The rest of this post walks the last mile: what changed when NumPy could finally call BLAS, and what OpenBLAS 0.3.34 and the upcoming 0.3.35 deliver.
The last mile: NumPy links OpenBLAS
The final step was linking NumPy to an accelerated BLAS. The previous Emscripten-forge NumPy package (2.5.2 on emscripten-forge-4x) shipped without OpenBLAS, so np.matmul, @, and np.linalg fell back to portable C loops: naive implementations blind to cache hierarchy and SIMD. Matrix products spent most of their time on memory traffic rather than arithmetic. This is our no-BLAS baseline.
As of emscripten-forge/recipes#6310, the default NumPy on emscripten-forge-4x (2.5.3, build 3) links OpenBLAS 0.3.34 with WASM SIMD (TARGET=WASM128_GENERIC). This is now a stable, main-channel release. Calls to np.matmul, @, and np.linalg.solve now dispatch to the accelerated BLAS in WebAssembly.
The packaging model is what makes this powerful. Emscripten-forge is, in effect, a conda-forge for WebAssembly: packages are built from recipes, published on conda channels, and installed with a package manager under a shared ABI: the same workflow as on linux-64, but targeting emscripten-wasm32. On that model, OpenBLAS is a separate conda package. NumPy dynamically links libopenblas at runtime, so you can upgrade OpenBLAS without rebuilding NumPy. This benefits the entire ecosystem: Scientific Python projects like SciPy and scikit-learn, as well as non-Python stacks such as xtensor-blas, all share the same library. PyPI NumPy wheels, by contrast, vendor a BLAS snapshot at build time. The same NumPy 2.5.3 package will thus automatically use OpenBLAS 0.3.35 once it's published.
OpenBLAS 0.3.34 versus no BLAS
Relative to the same Emscripten-forge stack without a BLAS implementation, square np.matmul at n = 1024 reaches about 30.92× (float32) and 14.90× (float64) (28.0 / 14.6 GFLOPS versus 0.90 / 0.98 GFLOPS). Full size grids and a single-thread linux-64 reference are in Appendix F; focused graphs and tables for this comparison are in Appendix B.
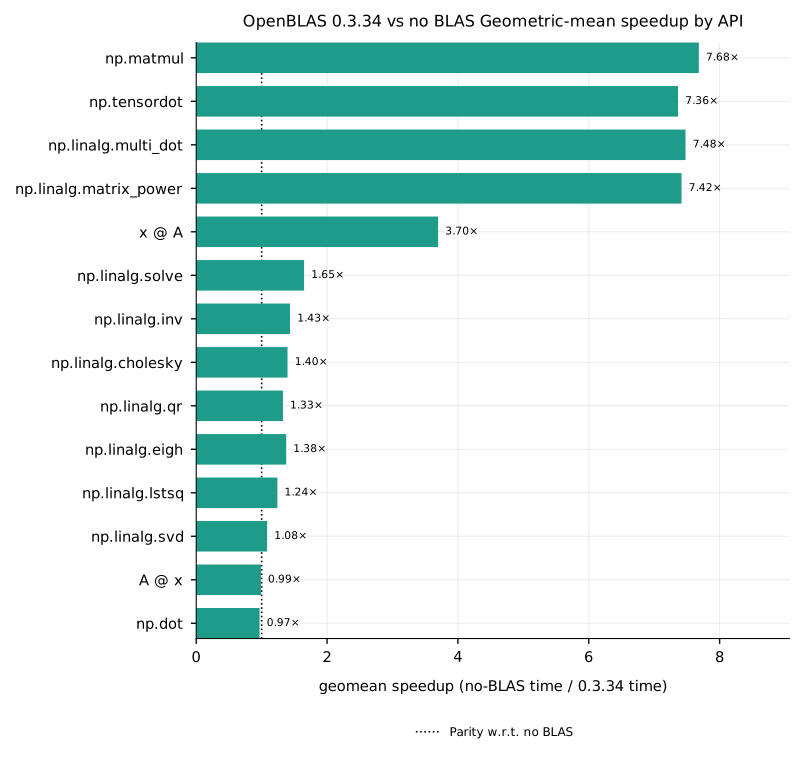
Geometric mean over both dtypes and the size grid (OpenBLAS 0.3.34 time in the denominator). Matrix products benefit most. Some np.linalg.* APIs see smaller gains (1.08–1.65× versus no BLAS) because they delegate to LAPACK, whose implementation in OpenBLAS is not yet optimized or specialized for WebAssembly. A @ x and vector np.dot remain near 1×: OpenBLAS 0.3.34 does not provide a fast column-major GEMV for that layout. OpenBLAS 0.3.35 adds that kernel.
Without BLAS, np.matmul throughput decreases with n (naive GEMM, cache misses). With OpenBLAS 0.3.34 it increases with n. Operations implemented on top of GEMM (@, two-dimensional np.dot, np.tensordot, np.linalg.multi_dot) follow the same trend. Speedup versus n and the associated numbers are in Appendix B.
On np.linalg at n = 1024 (float32), median times drop by about 1.2–2.1× versus no BLAS (solve 2.11×, cholesky 1.88×, qr 2.03×, inv 1.66×, eigh 1.60×, svd 1.21×; float64 agrees to within a few percent). For matrix–vector products, x @ A already uses a Level-2 kernel in 0.3.34 (14.86× at float32, n = 1024), while A @ x stays near the no-BLAS ~4 GFLOPS (1.02×).
OpenBLAS 0.3.35 will be even faster
The next OpenBLAS release includes WASM SIMD work already on develop. The numbers below use the openblas-experimental packages published by emscripten-forge/recipes#6761 (0.3.35.dev0, develop @ 539bb47, still TARGET=WASM128_GENERIC): portable simd128_hbf81ecf_3 (default) and opt-in relaxed_simd_h13a9a80_3. WebAssembly Relaxed SIMD is an engine extension that allows slightly looser floating-point semantics (notably fused multiply-add) in exchange for faster vector math; OpenBLAS can use those opcodes when the build enables them. Unless noted, 0.3.35 in this post means the portable SIMD128 build.
QuantStack contributed the WASM SIMD kernels upstream to OpenBLAS (Julien Jerphanion, Matthias Meschede), with review and integration by Martin Kroeker. That work covers Level-3 GEMM/TRMM, Level-1/2 AXPY and GEMV, numerical CBLAS tests for Node/Emscripten, and the optional Relaxed SIMD path. Portable SIMD128 remains the default: Relaxed SIMD FMA stays off unless you opt into the relaxed_simd build. The headline float32 GEMM step from 0.3.34 is an 8×4 microkernel; the optional Relaxed SIMD variant is covered in the next subsection.
Versus WASM OpenBLAS 0.3.34 at n = 1024, np.matmul improves by 1.79× (float32, 28.0 → 50.0 GFLOPS) and 1.41× (float64, 14.6 → 20.5 GFLOPS). Graphs and numbers for this comparison are in Appendix C; the complete grid is in Appendix F.
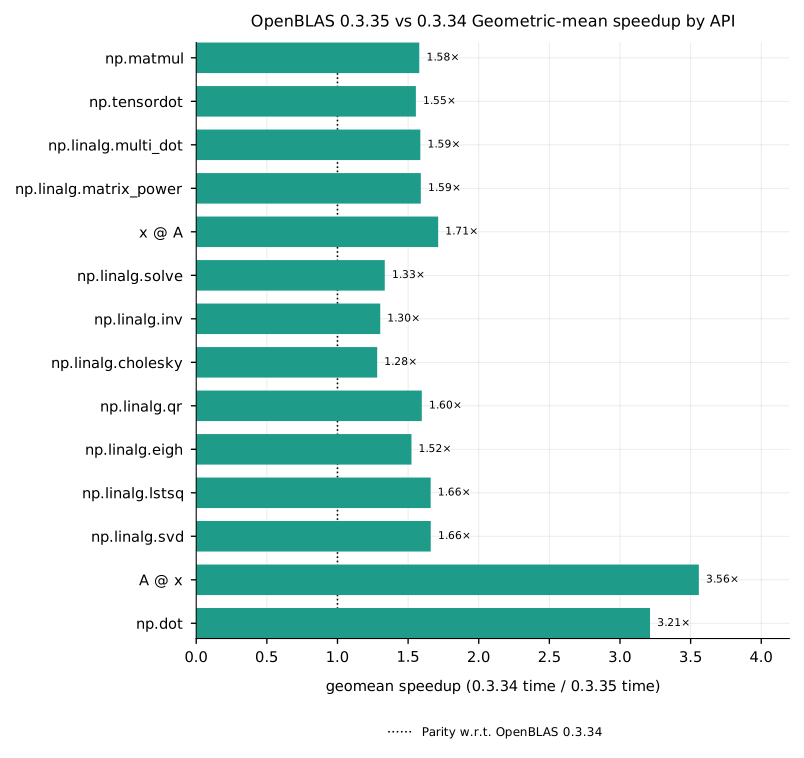
Geometric mean over both dtypes and the size grid (OpenBLAS 0.3.35 time in the denominator). The largest relative gains versus WASM 0.3.34 are not only in GEMM: A @ x jumps from the no-BLAS ~4 GFLOPS to 23.1 GFLOPS (float32, n = 1024) via the GEMV kernels (5.52× versus 0.3.34; x @ A is 1.73×). Vector np.dot improves similarly. Square np.matmul is 1.58× in geometric mean (and 1.79× at n = 1024 float32 from the 8×4 SGEMM). On np.linalg at n = 1024 float32, median times improve by about 1.3–1.9× versus 0.3.34 (solve 1.38×, cholesky 1.32×, qr 1.49×, inv 1.33×, eigh 1.64×, svd 1.90×).
Optional: Relaxed SIMD on top of 0.3.35
Engines that implement WebAssembly Relaxed SIMD can load the relaxed_simd OpenBLAS build (WASM_RELAXED_SIMD=1), which uses FMA-style v_muladd from #6001 / #6020. On Chromium 153 in this bench, that is another 1.17× (float32) and 1.43× (float64) on np.matmul at n = 1024 versus portable 0.3.35 (50.0 → 58.7 GFLOPS and 20.5 → 29.4 GFLOPS). Geometric-mean gains versus SIMD128 are largest on matrix products (~1.3×); Level-2 and most of np.linalg move by about 1.0–1.2×. Graphs and numbers for this comparison are in Appendix D.
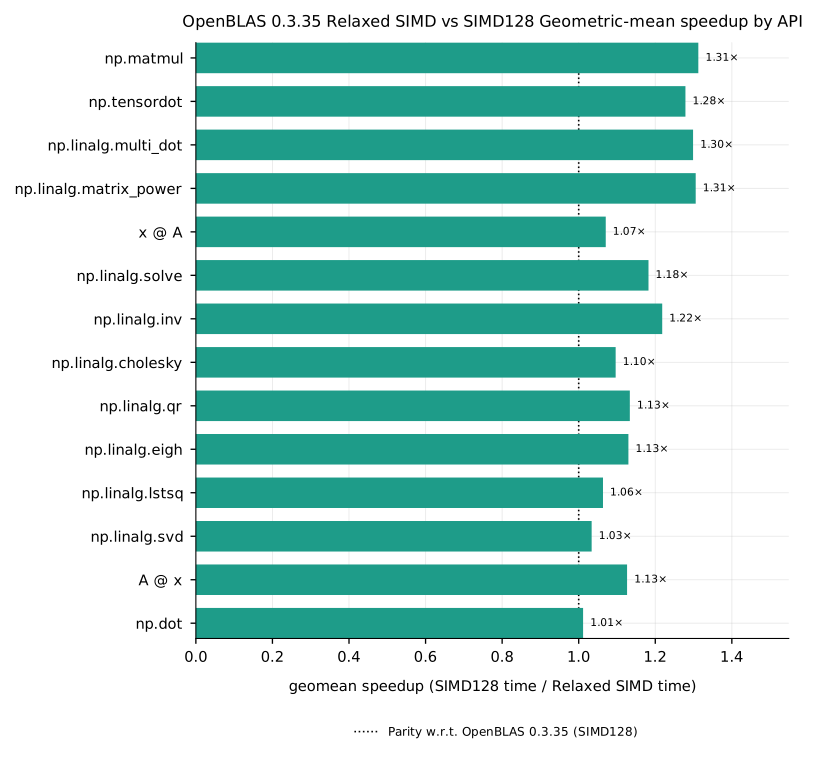
Chrome ≥114 and Firefox ≥146 expose the feature; Safari needs the JavaScriptCore flag useWebAssemblyRelaxedSIMD or the module fails to instantiate. The portable simd128 package remains the default for that reason (emscripten-forge/recipes#6761 down-prioritizes the Relaxed SIMD variant). Current engine support is tracked at webassembly.org/features.
From no BLAS to OpenBLAS 0.3.35
Putting the steps together (linking OpenBLAS 0.3.34, then picking up the 0.3.35 SIMD128 kernels, then optionally Relaxed SIMD) is the speedup path from the previous no-BLAS Emscripten-forge NumPy.
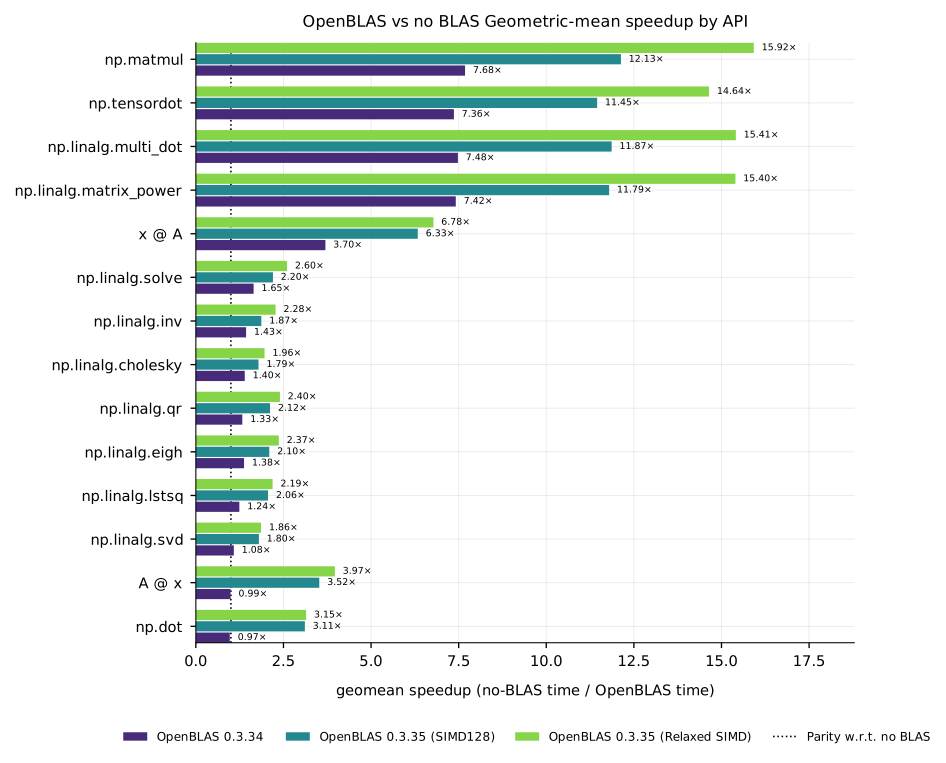
Geometric mean over both dtypes and the size grid (no-BLAS time in the numerator). Each API shows three bars: OpenBLAS 0.3.34, OpenBLAS 0.3.35 (SIMD128), and OpenBLAS 0.3.35 (Relaxed SIMD). Matrix products gain the most; Level-2 A @ x and vector np.dot finally move once the 0.3.35 GEMV kernels land; np.linalg.* sits in a smaller but still clear band above 1×, limited by LAPACK routines that are not yet WASM-specialized in OpenBLAS. NumPy as published on Emscripten-forge already delivers the OpenBLAS 0.3.34 half of that path; portable 0.3.35 (simd128_hbf81ecf_3 from emscripten-forge/recipes#6761) is on the experimental channel today, with the optional Relaxed SIMD build (relaxed_simd_h13a9a80_3) for supporting engines. End-to-end np.matmul at n = 1024 reaches about 64.89× (float32) and 30.07× (float64) versus no BLAS with Relaxed SIMD. Speedup versus n for this end-to-end comparison is in Appendix E; the complete size grid, including linux-64, is in Appendix F.
Using the packages
NumPy linked against OpenBLAS is on the main emscripten-forge-4x channel (as of emscripten-forge/recipes#6310). No experimental channel is required for that combination: install numpy and it pulls in OpenBLAS 0.3.34.
As an example, an environment for JupyterLite or notebook.link:
name: numpy-openblas
channels:
  - https://prefix.dev/emscripten-forge-4x
  - https://prefix.dev/conda-forge
dependencies:
  - xeus-python
  - numpy
OpenBLAS 0.3.35 (0.3.35.dev0) is on emscripten-forge-4x-experimental as the dual-variant packages from emscripten-forge/recipes#6761 (openblas-0.3.35.dev0-simd128_hbf81ecf_3 and openblas-0.3.35.dev0-relaxed_simd_h13a9a80_3). Add the experimental channel when you want the newer OpenBLAS without rebuilding NumPy, and pin the build string explicitly if you need Relaxed SIMD:
name: numpy-openblas-035
channels:
  - https://prefix.dev/emscripten-forge-4x
  - https://prefix.dev/emscripten-forge-4x-experimental
  - https://prefix.dev/conda-forge
dependencies:
  - xeus-python
  - numpy
  - openblas * *simd128*        # SIMD128 portable build (default)
  # - openblas * *relaxed_simd* # Relaxed SIMD build (not as portable, and deprioritized)
The portable simd128 default does not require WebAssembly Relaxed SIMD. The relaxed_simd package does: Chrome ≥114 and Firefox ≥146 work; Safari needs the JavaScriptCore flag useWebAssemblyRelaxedSIMD or the environment fails to load.
Conclusion
NumPy on Emscripten-forge can now call an accelerated BLAS in WebAssembly: linking OpenBLAS 0.3.34 already delivers large gains on matrix products and np.linalg, and the upcoming 0.3.35 kernels (with an optional Relaxed SIMD build) push further. Because that work landed upstream in OpenBLAS and as redistributable conda packages, the same improvements can benefit other WebAssembly Python stacks, including Pyodide, when they adopt an OpenBLAS build and the Fortran toolchain pieces from Emscripten-forge.
About the authors
- Julien Jerphanion (QuantStack) contributed the WebAssembly kernels upstream to OpenBLAS, designed and ran the benchmarks in this post, added numerical tests upstream, and packaged and tested NumPy and SciPy in the Emscripten-forge OpenBLAS recipe.
- Matthias Meschede (QuantStack) contributed to OpenBLAS to ensure that the WebAssembly kernels were indeed used, and provided help with package management.
- Ian Thomas (QuantStack) authored the initial patches to OpenBLAS that enabled its use by SciPy and other Emscripten-forge packages, some of which may be upstreamed into the OpenBLAS project.
Acknowledgements
Beyond the authors of this post, thanks to the people and communities who built the road this post only measures at the end:
- Isabel Paredes and Serge Guelton, for the Flang patches that made Fortran-on-
wasm32practical (building on George Stagg's work); Serge Guelton for upstreaming parts of that work into LLVM; and Isabel Paredes for maintainingflang_emscripten-wasm32on Emscripten-forge. - Martin Kroeker, core OpenMathLib / OpenBLAS maintainer, for reviewing and integrating our contributions.
- Sylvain Corlay, Isabel Paredes, and Antoine Pitrou, for comments that improved this post.
Appendix A: Benchmark settings
WebAssembly numbers are median-time speedups. Tables also give median time and GFLOPS. The linux-64 column is the same API grid on this machine.
| Setting | Value |
|---|---|
| Host | Dell XPS 15 9530, 13th Gen Intel Core i7-13700H (6P+8E, 20 threads, AVX2, up to 5.0 GHz), 64 GB RAM, Fedora Linux 44 |
| WebAssembly | Chromium 153; OpenBLAS USE_THREAD=0 TARGET=WASM128_GENERIC; packages from emscripten-forge/recipes#6761: simd128_hbf81ecf_3 (default) and relaxed_simd_h13a9a80_3 (WASM_RELAXED_SIMD=1) |
| linux-64 | conda-forge linux-64 NumPy 2.5.2 and OpenBLAS 0.3.34 (DYNAMIC_ARCH, Haswell kernel), one thread (OPENBLAS_NUM_THREADS=1), pinned to a P-core |
| Matrix sizes | 64, 128, 256, 512, 1024 |
| Vector sizes | 10⁴, 10⁵, 10⁶ |
| dtypes | float32, float64 |
| Statistic | median of 10 samples after 5 warmups |
| Scripts | github.com/jjerphan/numpy-wasm-openblas-bench |
Appendix B: OpenBLAS 0.3.34 versus no BLAS
OpenBLAS 0.3.34 relative to the no-BLAS Emscripten-forge NumPy baseline.
Speedup versus input size
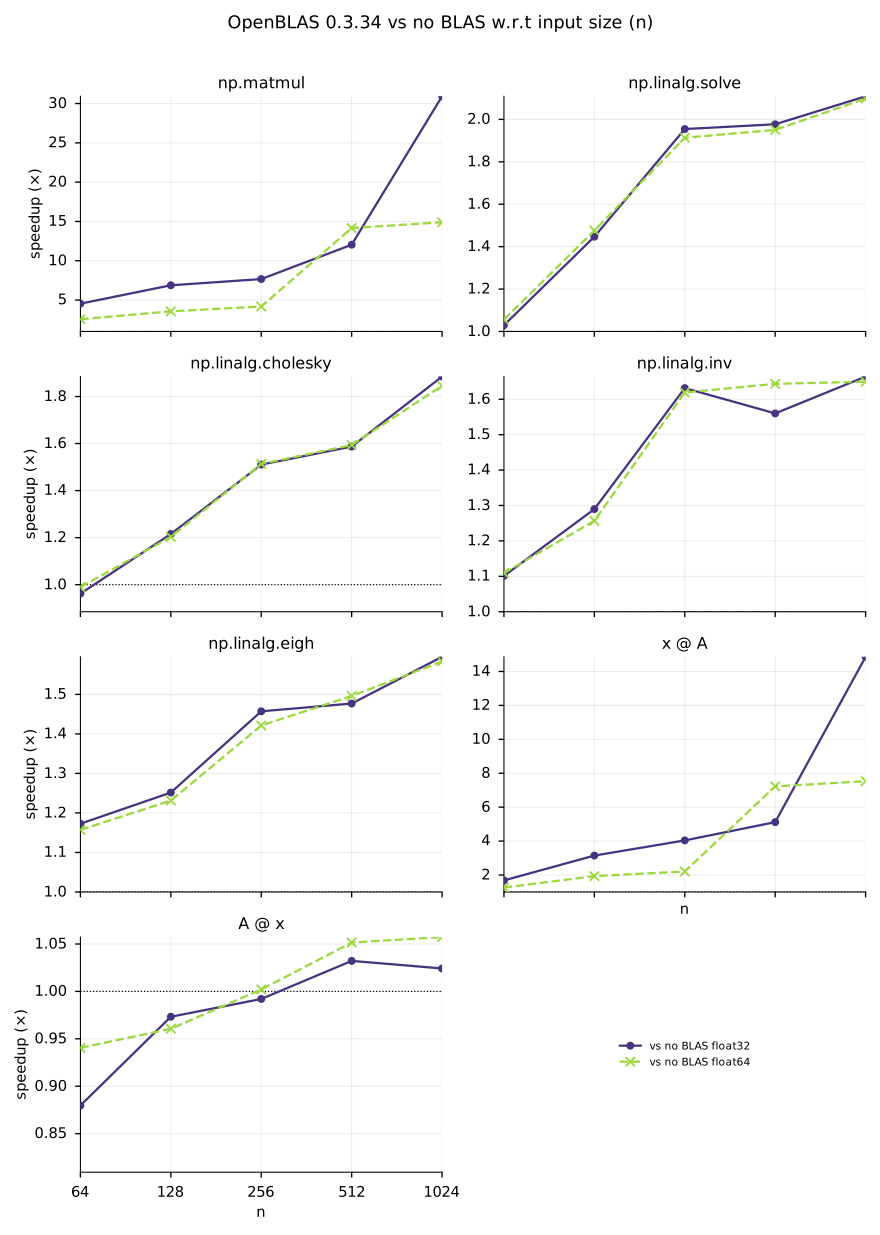
| API | n | dtype | 0.3.34 vs no BLAS |
|---|---|---|---|
np.matmul | 64 | float32 | 4.54× |
np.matmul | 64 | float64 | 2.56× |
np.matmul | 128 | float32 | 6.88× |
np.matmul | 128 | float64 | 3.56× |
np.matmul | 256 | float32 | 7.67× |
np.matmul | 256 | float64 | 4.17× |
np.matmul | 512 | float32 | 12.04× |
np.matmul | 512 | float64 | 14.16× |
np.matmul | 1024 | float32 | 30.92× |
np.matmul | 1024 | float64 | 14.90× |
np.linalg.solve | 64 | float32 | 1.03× |
np.linalg.solve | 64 | float64 | 1.06× |
np.linalg.solve | 128 | float32 | 1.45× |
np.linalg.solve | 128 | float64 | 1.48× |
np.linalg.solve | 256 | float32 | 1.95× |
np.linalg.solve | 256 | float64 | 1.91× |
np.linalg.solve | 512 | float32 | 1.98× |
np.linalg.solve | 512 | float64 | 1.95× |
np.linalg.solve | 1024 | float32 | 2.11× |
np.linalg.solve | 1024 | float64 | 2.10× |
np.linalg.cholesky | 64 | float32 | 0.96× |
np.linalg.cholesky | 64 | float64 | 0.99× |
np.linalg.cholesky | 128 | float32 | 1.22× |
np.linalg.cholesky | 128 | float64 | 1.20× |
np.linalg.cholesky | 256 | float32 | 1.51× |
np.linalg.cholesky | 256 | float64 | 1.51× |
np.linalg.cholesky | 512 | float32 | 1.59× |
np.linalg.cholesky | 512 | float64 | 1.59× |
np.linalg.cholesky | 1024 | float32 | 1.88× |
np.linalg.cholesky | 1024 | float64 | 1.85× |
np.linalg.inv | 64 | float32 | 1.10× |
np.linalg.inv | 64 | float64 | 1.11× |
np.linalg.inv | 128 | float32 | 1.29× |
np.linalg.inv | 128 | float64 | 1.26× |
np.linalg.inv | 256 | float32 | 1.63× |
np.linalg.inv | 256 | float64 | 1.62× |
np.linalg.inv | 512 | float32 | 1.56× |
np.linalg.inv | 512 | float64 | 1.64× |
np.linalg.inv | 1024 | float32 | 1.66× |
np.linalg.inv | 1024 | float64 | 1.65× |
np.linalg.eigh | 64 | float32 | 1.17× |
np.linalg.eigh | 64 | float64 | 1.16× |
np.linalg.eigh | 128 | float32 | 1.25× |
np.linalg.eigh | 128 | float64 | 1.23× |
np.linalg.eigh | 256 | float32 | 1.46× |
np.linalg.eigh | 256 | float64 | 1.42× |
np.linalg.eigh | 512 | float32 | 1.48× |
np.linalg.eigh | 512 | float64 | 1.50× |
np.linalg.eigh | 1024 | float32 | 1.60× |
np.linalg.eigh | 1024 | float64 | 1.58× |
x @ A | 64 | float32 | 1.68× |
x @ A | 64 | float64 | 1.26× |
x @ A | 128 | float32 | 3.15× |
x @ A | 128 | float64 | 1.93× |
x @ A | 256 | float32 | 4.04× |
x @ A | 256 | float64 | 2.21× |
x @ A | 512 | float32 | 5.12× |
x @ A | 512 | float64 | 7.23× |
x @ A | 1024 | float32 | 14.86× |
x @ A | 1024 | float64 | 7.53× |
A @ x | 64 | float32 | 0.88× |
A @ x | 64 | float64 | 0.94× |
A @ x | 128 | float32 | 0.97× |
A @ x | 128 | float64 | 0.96× |
A @ x | 256 | float32 | 0.99× |
A @ x | 256 | float64 | 1.00× |
A @ x | 512 | float32 | 1.03× |
A @ x | 512 | float64 | 1.05× |
A @ x | 1024 | float32 | 1.02× |
A @ x | 1024 | float64 | 1.06× |
Appendix C: OpenBLAS 0.3.35 (SIMD128) versus OpenBLAS 0.3.34
Portable OpenBLAS 0.3.35 (SIMD128) relative to WASM 0.3.34.
Speedup versus input size
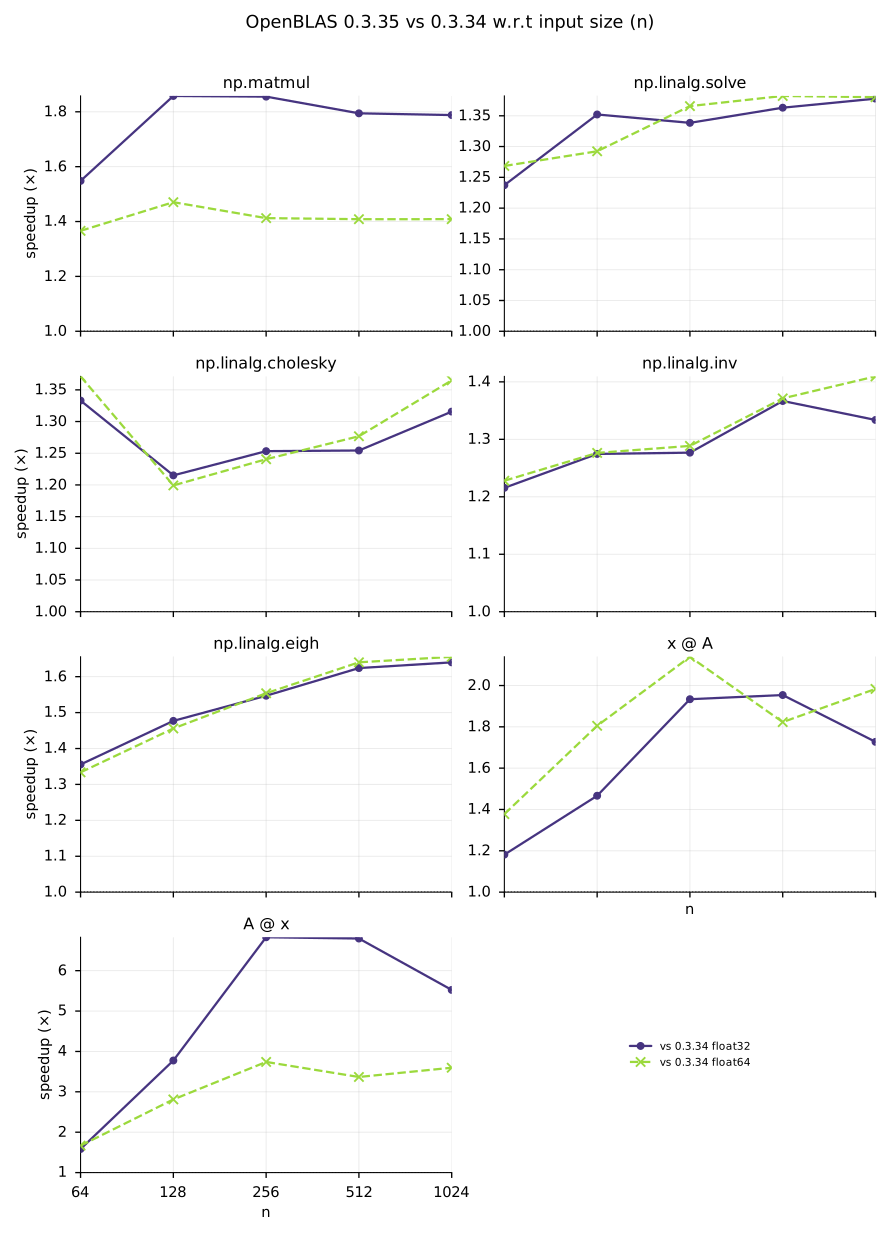
| API | n | dtype | 0.3.35 vs 0.3.34 |
|---|---|---|---|
np.matmul | 64 | float32 | 1.55× |
np.matmul | 64 | float64 | 1.37× |
np.matmul | 128 | float32 | 1.86× |
np.matmul | 128 | float64 | 1.47× |
np.matmul | 256 | float32 | 1.86× |
np.matmul | 256 | float64 | 1.41× |
np.matmul | 512 | float32 | 1.79× |
np.matmul | 512 | float64 | 1.41× |
np.matmul | 1024 | float32 | 1.79× |
np.matmul | 1024 | float64 | 1.41× |
np.linalg.solve | 64 | float32 | 1.24× |
np.linalg.solve | 64 | float64 | 1.27× |
np.linalg.solve | 128 | float32 | 1.35× |
np.linalg.solve | 128 | float64 | 1.29× |
np.linalg.solve | 256 | float32 | 1.34× |
np.linalg.solve | 256 | float64 | 1.37× |
np.linalg.solve | 512 | float32 | 1.36× |
np.linalg.solve | 512 | float64 | 1.38× |
np.linalg.solve | 1024 | float32 | 1.38× |
np.linalg.solve | 1024 | float64 | 1.38× |
np.linalg.cholesky | 64 | float32 | 1.33× |
np.linalg.cholesky | 64 | float64 | 1.37× |
np.linalg.cholesky | 128 | float32 | 1.22× |
np.linalg.cholesky | 128 | float64 | 1.20× |
np.linalg.cholesky | 256 | float32 | 1.25× |
np.linalg.cholesky | 256 | float64 | 1.24× |
np.linalg.cholesky | 512 | float32 | 1.25× |
np.linalg.cholesky | 512 | float64 | 1.28× |
np.linalg.cholesky | 1024 | float32 | 1.32× |
np.linalg.cholesky | 1024 | float64 | 1.37× |
np.linalg.inv | 64 | float32 | 1.22× |
np.linalg.inv | 64 | float64 | 1.23× |
np.linalg.inv | 128 | float32 | 1.27× |
np.linalg.inv | 128 | float64 | 1.28× |
np.linalg.inv | 256 | float32 | 1.28× |
np.linalg.inv | 256 | float64 | 1.29× |
np.linalg.inv | 512 | float32 | 1.37× |
np.linalg.inv | 512 | float64 | 1.37× |
np.linalg.inv | 1024 | float32 | 1.33× |
np.linalg.inv | 1024 | float64 | 1.41× |
np.linalg.eigh | 64 | float32 | 1.36× |
np.linalg.eigh | 64 | float64 | 1.33× |
np.linalg.eigh | 128 | float32 | 1.48× |
np.linalg.eigh | 128 | float64 | 1.46× |
np.linalg.eigh | 256 | float32 | 1.55× |
np.linalg.eigh | 256 | float64 | 1.55× |
np.linalg.eigh | 512 | float32 | 1.62× |
np.linalg.eigh | 512 | float64 | 1.64× |
np.linalg.eigh | 1024 | float32 | 1.64× |
np.linalg.eigh | 1024 | float64 | 1.66× |
x @ A | 64 | float32 | 1.18× |
x @ A | 64 | float64 | 1.38× |
x @ A | 128 | float32 | 1.47× |
x @ A | 128 | float64 | 1.80× |
x @ A | 256 | float32 | 1.93× |
x @ A | 256 | float64 | 2.14× |
x @ A | 512 | float32 | 1.95× |
x @ A | 512 | float64 | 1.82× |
x @ A | 1024 | float32 | 1.73× |
x @ A | 1024 | float64 | 1.98× |
A @ x | 64 | float32 | 1.58× |
A @ x | 64 | float64 | 1.67× |
A @ x | 128 | float32 | 3.78× |
A @ x | 128 | float64 | 2.81× |
A @ x | 256 | float32 | 6.83× |
A @ x | 256 | float64 | 3.74× |
A @ x | 512 | float32 | 6.80× |
A @ x | 512 | float64 | 3.37× |
A @ x | 1024 | float32 | 5.52× |
A @ x | 1024 | float64 | 3.60× |
Appendix D: OpenBLAS 0.3.35 (Relaxed SIMD) versus OpenBLAS 0.3.35 (SIMD128)
Opt-in relaxed_simd OpenBLAS (WASM_RELAXED_SIMD=1, Relaxed SIMD) versus the portable simd128 0.3.35 default on Chromium 153.
Speedup versus input size
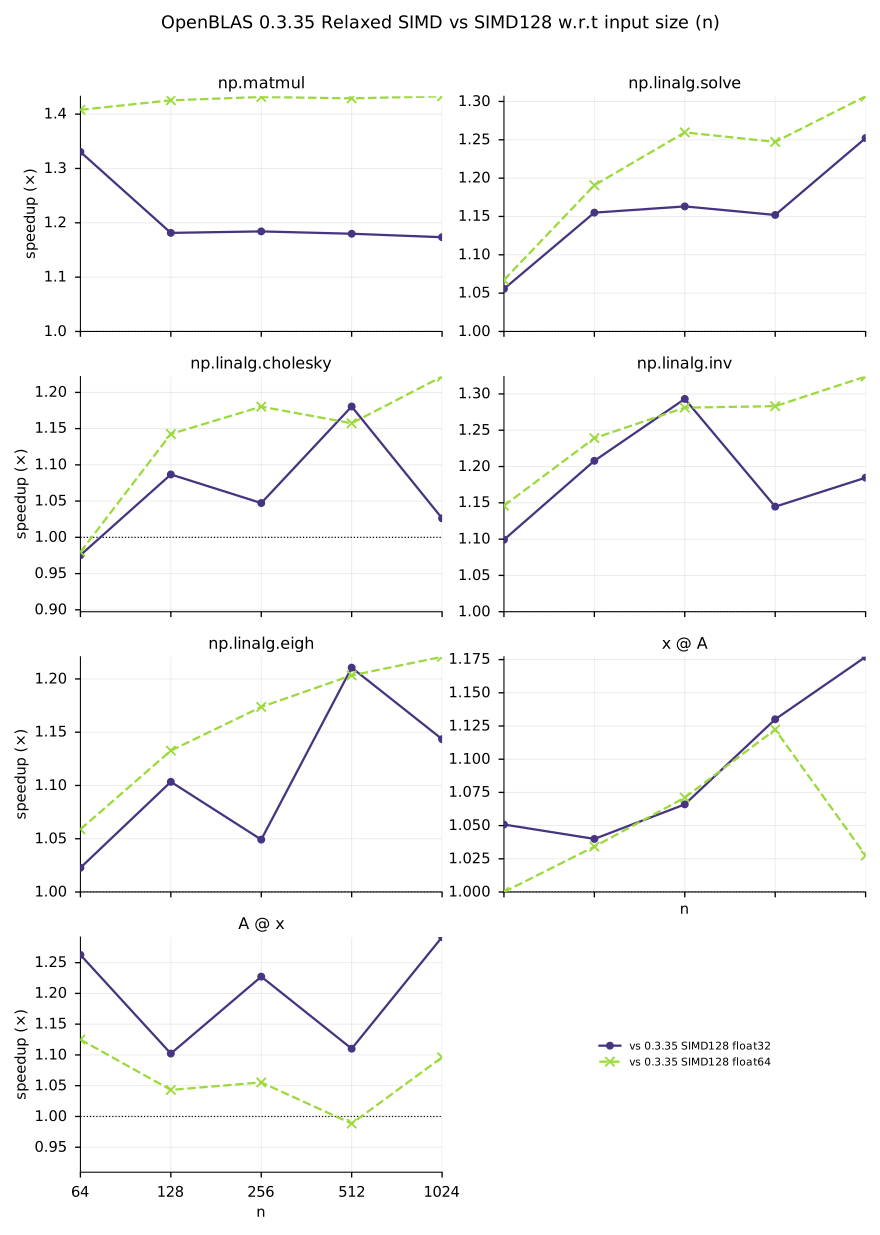
| API | n | dtype | Relaxed SIMD vs SIMD128 |
|---|---|---|---|
np.matmul | 64 | float32 | 1.33× |
np.matmul | 64 | float64 | 1.41× |
np.matmul | 128 | float32 | 1.18× |
np.matmul | 128 | float64 | 1.43× |
np.matmul | 256 | float32 | 1.18× |
np.matmul | 256 | float64 | 1.43× |
np.matmul | 512 | float32 | 1.18× |
np.matmul | 512 | float64 | 1.43× |
np.matmul | 1024 | float32 | 1.17× |
np.matmul | 1024 | float64 | 1.43× |
np.linalg.solve | 64 | float32 | 1.06× |
np.linalg.solve | 64 | float64 | 1.07× |
np.linalg.solve | 128 | float32 | 1.16× |
np.linalg.solve | 128 | float64 | 1.19× |
np.linalg.solve | 256 | float32 | 1.16× |
np.linalg.solve | 256 | float64 | 1.26× |
np.linalg.solve | 512 | float32 | 1.15× |
np.linalg.solve | 512 | float64 | 1.25× |
np.linalg.solve | 1024 | float32 | 1.25× |
np.linalg.solve | 1024 | float64 | 1.31× |
np.linalg.cholesky | 64 | float32 | 0.98× |
np.linalg.cholesky | 64 | float64 | 0.98× |
np.linalg.cholesky | 128 | float32 | 1.09× |
np.linalg.cholesky | 128 | float64 | 1.14× |
np.linalg.cholesky | 256 | float32 | 1.05× |
np.linalg.cholesky | 256 | float64 | 1.18× |
np.linalg.cholesky | 512 | float32 | 1.18× |
np.linalg.cholesky | 512 | float64 | 1.16× |
np.linalg.cholesky | 1024 | float32 | 1.03× |
np.linalg.cholesky | 1024 | float64 | 1.22× |
np.linalg.inv | 64 | float32 | 1.10× |
np.linalg.inv | 64 | float64 | 1.15× |
np.linalg.inv | 128 | float32 | 1.21× |
np.linalg.inv | 128 | float64 | 1.24× |
np.linalg.inv | 256 | float32 | 1.29× |
np.linalg.inv | 256 | float64 | 1.28× |
np.linalg.inv | 512 | float32 | 1.14× |
np.linalg.inv | 512 | float64 | 1.28× |
np.linalg.inv | 1024 | float32 | 1.18× |
np.linalg.inv | 1024 | float64 | 1.32× |
np.linalg.eigh | 64 | float32 | 1.02× |
np.linalg.eigh | 64 | float64 | 1.06× |
np.linalg.eigh | 128 | float32 | 1.10× |
np.linalg.eigh | 128 | float64 | 1.13× |
np.linalg.eigh | 256 | float32 | 1.05× |
np.linalg.eigh | 256 | float64 | 1.17× |
np.linalg.eigh | 512 | float32 | 1.21× |
np.linalg.eigh | 512 | float64 | 1.20× |
np.linalg.eigh | 1024 | float32 | 1.14× |
np.linalg.eigh | 1024 | float64 | 1.22× |
x @ A | 64 | float32 | 1.05× |
x @ A | 64 | float64 | 1.00× |
x @ A | 128 | float32 | 1.04× |
x @ A | 128 | float64 | 1.03× |
x @ A | 256 | float32 | 1.07× |
x @ A | 256 | float64 | 1.07× |
x @ A | 512 | float32 | 1.13× |
x @ A | 512 | float64 | 1.12× |
x @ A | 1024 | float32 | 1.18× |
x @ A | 1024 | float64 | 1.03× |
A @ x | 64 | float32 | 1.26× |
A @ x | 64 | float64 | 1.13× |
A @ x | 128 | float32 | 1.10× |
A @ x | 128 | float64 | 1.04× |
A @ x | 256 | float32 | 1.23× |
A @ x | 256 | float64 | 1.06× |
A @ x | 512 | float32 | 1.11× |
A @ x | 512 | float64 | 0.99× |
A @ x | 1024 | float32 | 1.29× |
A @ x | 1024 | float64 | 1.10× |
Appendix E: All changes: OpenBLAS 0.3.35 (Relaxed SIMD) versus no BLAS
End-to-end speedup from the no-BLAS Emscripten-forge NumPy baseline to OpenBLAS 0.3.35 with Relaxed SIMD (the full path: linking OpenBLAS, portable 0.3.35 kernels, then Relaxed SIMD).
Speedup versus input size
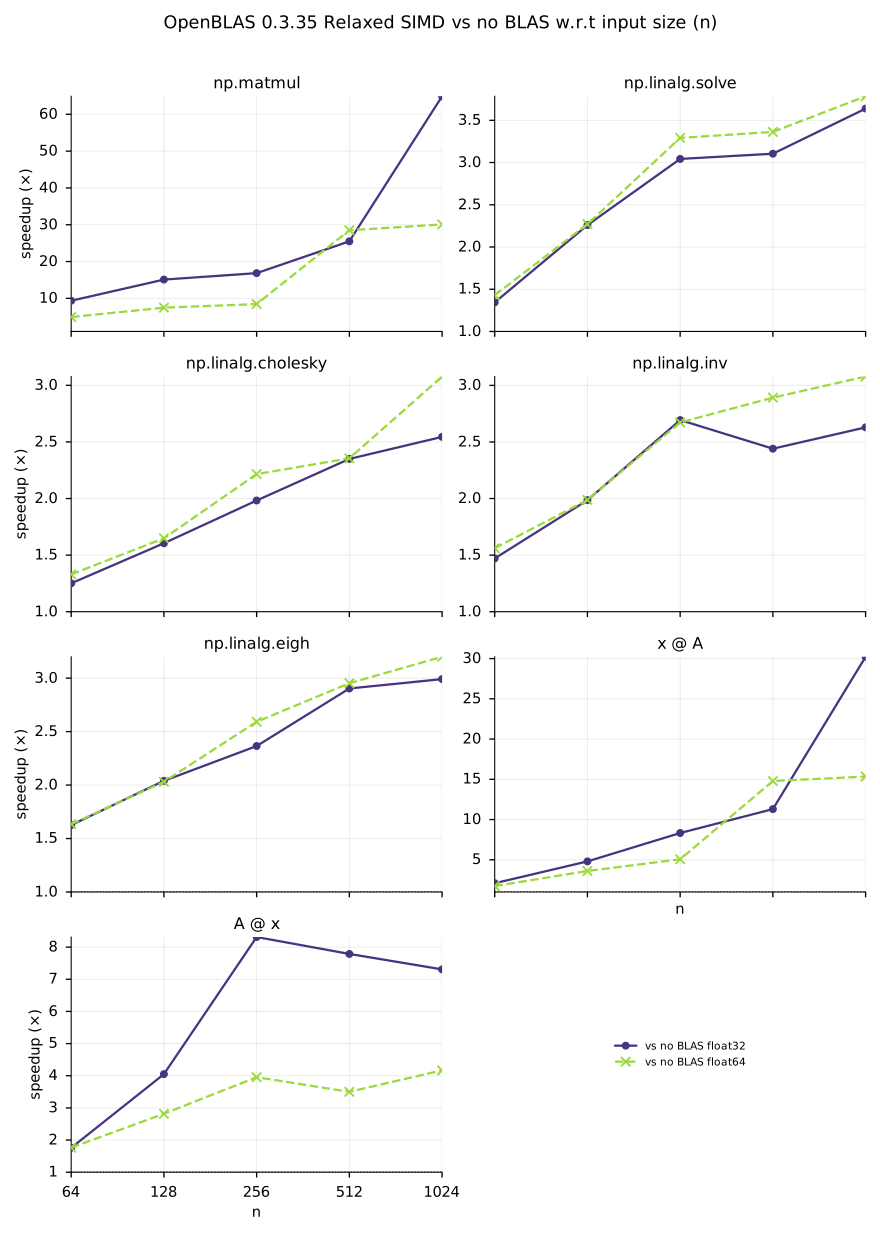
| API | n | dtype | Relaxed SIMD vs no BLAS |
|---|---|---|---|
np.matmul | 64 | float32 | 9.35× |
np.matmul | 64 | float64 | 4.92× |
np.matmul | 128 | float32 | 15.10× |
np.matmul | 128 | float64 | 7.46× |
np.matmul | 256 | float32 | 16.85× |
np.matmul | 256 | float64 | 8.44× |
np.matmul | 512 | float32 | 25.49× |
np.matmul | 512 | float64 | 28.50× |
np.matmul | 1024 | float32 | 64.89× |
np.matmul | 1024 | float64 | 30.07× |
np.linalg.solve | 64 | float32 | 1.34× |
np.linalg.solve | 64 | float64 | 1.43× |
np.linalg.solve | 128 | float32 | 2.26× |
np.linalg.solve | 128 | float64 | 2.27× |
np.linalg.solve | 256 | float32 | 3.04× |
np.linalg.solve | 256 | float64 | 3.29× |
np.linalg.solve | 512 | float32 | 3.10× |
np.linalg.solve | 512 | float64 | 3.36× |
np.linalg.solve | 1024 | float32 | 3.64× |
np.linalg.solve | 1024 | float64 | 3.78× |
np.linalg.cholesky | 64 | float32 | 1.25× |
np.linalg.cholesky | 64 | float64 | 1.33× |
np.linalg.cholesky | 128 | float32 | 1.61× |
np.linalg.cholesky | 128 | float64 | 1.65× |
np.linalg.cholesky | 256 | float32 | 1.98× |
np.linalg.cholesky | 256 | float64 | 2.22× |
np.linalg.cholesky | 512 | float32 | 2.35× |
np.linalg.cholesky | 512 | float64 | 2.36× |
np.linalg.cholesky | 1024 | float32 | 2.54× |
np.linalg.cholesky | 1024 | float64 | 3.08× |
np.linalg.inv | 64 | float32 | 1.47× |
np.linalg.inv | 64 | float64 | 1.56× |
np.linalg.inv | 128 | float32 | 1.99× |
np.linalg.inv | 128 | float64 | 1.99× |
np.linalg.inv | 256 | float32 | 2.69× |
np.linalg.inv | 256 | float64 | 2.67× |
np.linalg.inv | 512 | float32 | 2.44× |
np.linalg.inv | 512 | float64 | 2.89× |
np.linalg.inv | 1024 | float32 | 2.63× |
np.linalg.inv | 1024 | float64 | 3.08× |
np.linalg.eigh | 64 | float32 | 1.63× |
np.linalg.eigh | 64 | float64 | 1.63× |
np.linalg.eigh | 128 | float32 | 2.04× |
np.linalg.eigh | 128 | float64 | 2.03× |
np.linalg.eigh | 256 | float32 | 2.37× |
np.linalg.eigh | 256 | float64 | 2.59× |
np.linalg.eigh | 512 | float32 | 2.90× |
np.linalg.eigh | 512 | float64 | 2.95× |
np.linalg.eigh | 1024 | float32 | 2.99× |
np.linalg.eigh | 1024 | float64 | 3.20× |
x @ A | 64 | float32 | 2.09× |
x @ A | 64 | float64 | 1.74× |
x @ A | 128 | float32 | 4.80× |
x @ A | 128 | float64 | 3.61× |
x @ A | 256 | float32 | 8.33× |
x @ A | 256 | float64 | 5.06× |
x @ A | 512 | float32 | 11.30× |
x @ A | 512 | float64 | 14.78× |
x @ A | 1024 | float32 | 30.22× |
x @ A | 1024 | float64 | 15.35× |
A @ x | 64 | float32 | 1.76× |
A @ x | 64 | float64 | 1.76× |
A @ x | 128 | float32 | 4.05× |
A @ x | 128 | float64 | 2.82× |
A @ x | 256 | float32 | 8.31× |
A @ x | 256 | float64 | 3.95× |
A @ x | 512 | float32 | 7.79× |
A @ x | 512 | float64 | 3.50× |
A @ x | 1024 | float32 | 7.31× |
A @ x | 1024 | float64 | 4.17× |
Appendix F: Full benchmark results (including linux-64)
Absolute throughput and speedups for OpenBLAS 0.3.34, OpenBLAS 0.3.35 (SIMD128), the optional 0.3.35 Relaxed SIMD build, and a single-thread conda-forge linux-64 OpenBLAS 0.3.34 reference on the same machine. Speedup is baseline time divided by featured time (>1 means the featured stack is faster).
Geometric-mean speedups by API
| API | 0.3.34 vs no BLAS | 0.3.34 vs linux-64 | 0.3.35 vs 0.3.34 | 0.3.35 vs no BLAS | 0.3.35 vs linux-64 | Relaxed SIMD vs 0.3.35 | Relaxed SIMD vs no BLAS | Relaxed SIMD vs linux-64 |
|---|---|---|---|---|---|---|---|---|
np.matmul | 7.68× | 0.25× | 1.58× | 12.13× | 0.39× | 1.31× | 15.92× | 0.51× |
np.tensordot | 7.36× | 0.26× | 1.55× | 11.45× | 0.40× | 1.28× | 14.64× | 0.51× |
np.linalg.multi_dot | 7.48× | 0.25× | 1.59× | 11.87× | 0.40× | 1.30× | 15.41× | 0.51× |
np.linalg.matrix_power | 7.42× | 0.25× | 1.59× | 11.79× | 0.39× | 1.31× | 15.40× | 0.51× |
x @ A | 3.70× | 0.38× | 1.71× | 6.33× | 0.65× | 1.07× | 6.78× | 0.70× |
np.linalg.solve | 1.65× | 0.45× | 1.33× | 2.20× | 0.61× | 1.18× | 2.60× | 0.72× |
np.linalg.inv | 1.43× | 0.42× | 1.30× | 1.87× | 0.55× | 1.22× | 2.28× | 0.66× |
np.linalg.cholesky | 1.40× | 0.46× | 1.28× | 1.79× | 0.59× | 1.10× | 1.96× | 0.65× |
np.linalg.qr | 1.33× | 0.39× | 1.60× | 2.12× | 0.63× | 1.13× | 2.40× | 0.71× |
np.linalg.eigh | 1.38× | 0.43× | 1.52× | 2.10× | 0.65× | 1.13× | 2.37× | 0.73× |
np.linalg.lstsq | 1.24× | 0.47× | 1.66× | 2.06× | 0.77× | 1.06× | 2.19× | 0.82× |
np.linalg.svd | 1.08× | 0.46× | 1.66× | 1.80× | 0.77× | 1.03× | 1.86× | 0.80× |
A @ x | 0.99× | 0.18× | 3.56× | 3.52× | 0.65× | 1.13× | 3.97× | 0.73× |
np.dot | 0.97× | 0.26× | 3.21× | 3.11× | 0.83× | 1.01× | 3.15× | 0.84× |
np.matmul across sizes (GFLOPS)
| n | dtype | no BLAS | OpenBLAS 0.3.34 | OpenBLAS 0.3.35 | 0.3.35 Relaxed SIMD | linux-64 | 0.3.34 vs no BLAS | 0.3.35 vs 0.3.34 | 0.3.35 vs no BLAS | Relaxed SIMD vs 0.3.35 | Relaxed SIMD vs no BLAS | 0.3.34 vs linux-64 | 0.3.35 vs linux-64 | Relaxed SIMD vs linux-64 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 64 | float32 | 4.74 | 21.5 | 33.3 | 44.3 | 84.7 | 4.54× | 1.55× | 7.03× | 1.33× | 9.35× | 0.25× | 0.39× | 0.52× |
| 64 | float64 | 5.01 | 12.8 | 17.5 | 24.7 | 44.1 | 2.56× | 1.37× | 3.50× | 1.41× | 4.92× | 0.29× | 0.40× | 0.56× |
| 128 | float32 | 3.57 | 24.5 | 45.6 | 53.9 | 110.4 | 6.88× | 1.86× | 12.78× | 1.18× | 15.10× | 0.22× | 0.41× | 0.49× |
| 128 | float64 | 3.76 | 13.4 | 19.7 | 28.0 | 52.9 | 3.56× | 1.47× | 5.24× | 1.43× | 7.46× | 0.25× | 0.37× | 0.53× |
| 256 | float32 | 3.38 | 25.9 | 48.0 | 56.9 | 120.5 | 7.67× | 1.86× | 14.23× | 1.18× | 16.85× | 0.21× | 0.40× | 0.47× |
| 256 | float64 | 3.42 | 14.3 | 20.2 | 28.9 | 55.5 | 4.17× | 1.41× | 5.90× | 1.43× | 8.44× | 0.26× | 0.36× | 0.52× |
| 512 | float32 | 2.29 | 27.5 | 49.4 | 58.3 | 118.6 | 12.04× | 1.79× | 21.61× | 1.18× | 25.49× | 0.23× | 0.42× | 0.49× |
| 512 | float64 | 1.02 | 14.5 | 20.4 | 29.2 | 56.8 | 14.16× | 1.41× | 19.95× | 1.43× | 28.50× | 0.26× | 0.36× | 0.51× |
| 1024 | float32 | 0.90 | 28.0 | 50.0 | 58.7 | 120.4 | 30.92× | 1.79× | 55.30× | 1.17× | 64.89× | 0.23× | 0.42× | 0.49× |
| 1024 | float64 | 0.98 | 14.6 | 20.5 | 29.4 | 57.2 | 14.90× | 1.41× | 20.99× | 1.43× | 30.07× | 0.25× | 0.36× | 0.51× |
np.linalg at n = 1024 (median time, ms)
| call | dtype | no BLAS | OpenBLAS 0.3.34 | OpenBLAS 0.3.35 | 0.3.35 Relaxed SIMD | linux-64 | 0.3.34 vs no BLAS | 0.3.35 vs 0.3.34 | 0.3.35 vs no BLAS | Relaxed SIMD vs 0.3.35 | Relaxed SIMD vs no BLAS | 0.3.34 vs linux-64 | 0.3.35 vs linux-64 | Relaxed SIMD vs linux-64 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
np.linalg.solve | float32 | 122 | 58 | 42 | 34 | 21 | 2.11× | 1.38× | 2.91× | 1.25× | 3.64× | 0.36× | 0.49× | 0.61× |
np.linalg.solve | float64 | 118 | 56 | 41 | 31 | 21 | 2.10× | 1.38× | 2.90× | 1.31× | 3.78× | 0.37× | 0.51× | 0.67× |
np.linalg.cholesky | float32 | 68 | 36 | 27 | 27 | 16 | 1.88× | 1.32× | 2.48× | 1.03× | 2.54× | 0.46× | 0.60× | 0.62× |
np.linalg.cholesky | float64 | 66 | 36 | 26 | 22 | 17 | 1.85× | 1.37× | 2.52× | 1.22× | 3.08× | 0.47× | 0.64× | 0.78× |
np.linalg.qr | float32 | 552 | 272 | 183 | 142 | 96 | 2.03× | 1.49× | 3.01× | 1.29× | 3.89× | 0.35× | 0.52× | 0.68× |
np.linalg.qr | float64 | 549 | 259 | 184 | 141 | 96 | 2.12× | 1.41× | 2.98× | 1.31× | 3.89× | 0.37× | 0.52× | 0.68× |
np.linalg.inv | float32 | 357 | 215 | 161 | 136 | 70 | 1.66× | 1.33× | 2.22× | 1.18× | 2.63× | 0.33× | 0.44× | 0.52× |
np.linalg.inv | float64 | 364 | 221 | 157 | 118 | 72 | 1.65× | 1.41× | 2.33× | 1.32× | 3.08× | 0.33× | 0.46× | 0.61× |
np.linalg.eigh | float32 | 793 | 497 | 303 | 265 | 171 | 1.60× | 1.64× | 2.62× | 1.14× | 2.99× | 0.34× | 0.57× | 0.65× |
np.linalg.eigh | float64 | 778 | 491 | 297 | 243 | 165 | 1.58× | 1.66× | 2.62× | 1.22× | 3.20× | 0.34× | 0.56× | 0.68× |
np.linalg.svd | float32 | 569 | 471 | 248 | 253 | 205 | 1.21× | 1.90× | 2.29× | 0.98× | 2.25× | 0.44× | 0.83× | 0.81× |
np.linalg.svd | float64 | 571 | 487 | 258 | 235 | 215 | 1.17× | 1.89× | 2.21× | 1.10× | 2.43× | 0.44× | 0.83× | 0.92× |
Matrix–vector @ across sizes (GFLOPS)
| call | n | dtype | no BLAS | OpenBLAS 0.3.34 | OpenBLAS 0.3.35 | 0.3.35 Relaxed SIMD | linux-64 | 0.3.34 vs no BLAS | 0.3.35 vs 0.3.34 | 0.3.35 vs no BLAS | Relaxed SIMD vs 0.3.35 | Relaxed SIMD vs no BLAS | 0.3.34 vs linux-64 | 0.3.35 vs linux-64 | Relaxed SIMD vs linux-64 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
x @ A | 64 | float32 | 2.94 | 4.94 | 5.84 | 6.14 | 12.0 | 1.68× | 1.18× | 1.99× | 1.05× | 2.09× | 0.41× | 0.49× | 0.51× |
x @ A | 64 | float64 | 2.95 | 3.72 | 5.12 | 5.12 | 9.57 | 1.26× | 1.38× | 1.74× | 1.00× | 1.74× | 0.39× | 0.54× | 0.54× |
x @ A | 128 | float32 | 3.12 | 9.81 | 14.4 | 15.0 | 27.5 | 3.15× | 1.47× | 4.62× | 1.04× | 4.80× | 0.36× | 0.52× | 0.54× |
x @ A | 128 | float64 | 3.03 | 5.85 | 10.6 | 10.9 | 18.6 | 1.93× | 1.80× | 3.49× | 1.03× | 3.61× | 0.31× | 0.57× | 0.59× |
x @ A | 256 | float32 | 3.27 | 13.2 | 25.6 | 27.2 | 42.0 | 4.04× | 1.93× | 7.81× | 1.07× | 8.33× | 0.31× | 0.61× | 0.65× |
x @ A | 256 | float64 | 3.23 | 7.13 | 15.3 | 16.3 | 25.1 | 2.21× | 2.14× | 4.73× | 1.07× | 5.06× | 0.28× | 0.61× | 0.65× |
x @ A | 512 | float32 | 2.69 | 13.8 | 26.9 | 30.4 | 43.2 | 5.12× | 1.95× | 10.00× | 1.13× | 11.30× | 0.32× | 0.62× | 0.70× |
x @ A | 512 | float64 | 1.02 | 7.35 | 13.4 | 15.0 | 14.1 | 7.23× | 1.82× | 13.17× | 1.12× | 14.78× | 0.52× | 0.95× | 1.06× |
x @ A | 1024 | float32 | 0.95 | 14.2 | 24.4 | 28.8 | 30.2 | 14.86× | 1.73× | 25.68× | 1.18× | 30.22× | 0.47× | 0.81× | 0.95× |
x @ A | 1024 | float64 | 1.00 | 7.50 | 14.9 | 15.3 | 14.3 | 7.53× | 1.98× | 14.94× | 1.03× | 15.35× | 0.53× | 1.04× | 1.07× |
A @ x | 64 | float32 | 2.91 | 2.56 | 4.06 | 5.12 | 10.7 | 0.88× | 1.58× | 1.39× | 1.26× | 1.76× | 0.24× | 0.38× | 0.48× |
A @ x | 64 | float64 | 2.89 | 2.72 | 4.53 | 5.10 | 9.79 | 0.94× | 1.67× | 1.57× | 1.13× | 1.76× | 0.28× | 0.46× | 0.52× |
A @ x | 128 | float32 | 4.05 | 3.94 | 14.9 | 16.4 | 24.2 | 0.97× | 3.78× | 3.67× | 1.10× | 4.05× | 0.16× | 0.61× | 0.68× |
A @ x | 128 | float64 | 4.01 | 3.85 | 10.8 | 11.3 | 19.9 | 0.96× | 2.81× | 2.70× | 1.04× | 2.82× | 0.19× | 0.55× | 0.57× |
A @ x | 256 | float32 | 4.26 | 4.22 | 28.8 | 35.4 | 38.5 | 0.99× | 6.83× | 6.77× | 1.23× | 8.31× | 0.11× | 0.75× | 0.92× |
A @ x | 256 | float64 | 4.19 | 4.20 | 15.7 | 16.6 | 28.6 | 1.00× | 3.74× | 3.75× | 1.06× | 3.95× | 0.15× | 0.55× | 0.58× |
A @ x | 512 | float32 | 4.12 | 4.26 | 28.9 | 32.1 | 42.6 | 1.03× | 6.80× | 7.01× | 1.11× | 7.79× | 0.10× | 0.68× | 0.75× |
A @ x | 512 | float64 | 4.07 | 4.28 | 14.4 | 14.2 | 15.2 | 1.05× | 3.37× | 3.54× | 0.99× | 3.50× | 0.28× | 0.95× | 0.94× |
A @ x | 1024 | float32 | 4.08 | 4.18 | 23.1 | 29.8 | 29.5 | 1.02× | 5.52× | 5.66× | 1.29× | 7.31× | 0.14× | 0.78× | 1.01× |
A @ x | 1024 | float64 | 4.02 | 4.25 | 15.3 | 16.7 | 14.9 | 1.06× | 3.60× | 3.80× | 1.10× | 4.17× | 0.28× | 1.02× | 1.12× |